Ranked by measurement
Best AI model benchmark leaderboard
69 tested · top 69 shown
8 more could only be measured on fewer than five frames, so they are not ranked here — a partial average is not comparable with a full one.
Ordered by a seven-frame production-readiness benchmark measured from each product's public surface — not popularity, pricing or feature count. Nobody pays to appear here and the order is never edited. How it is measured →
How this field scores
low 19median 75best 97
- 1BenchLMBenchLM compares LLM API pricing and benchmark scores across major providers.Perf 89Acce 97Sec 100Priv 100Rel 100Std 92Disc 100benchlm.ai · measured 2026-11-177/7 frames
- 2ORO SubnetORO is an open benchmark for AI shopping agents built on the Bittensor network.Perf 96Acce 100Sec 80Priv 100Rel 100Std 86Disc 100oroagents.com · measured 2026-11-117/7 frames
- 3AI Trading CompetitionA public paper-trading competition pitting GPT-5.6, Claude, Grok, and Gemini against each other.Perf 96Acce 100Sec 80Priv 100Rel 100Std 85Disc 100aitradingcompetition.com · measured 2026-11-197/7 frames
- 4
 HungryGPUHungryGPU tracks published LLM benchmark figures by machine and software stack.Perf 62Acce 96Sec 100Priv 100Rel 100Std 92Disc 100hungrygpu.com · measured 2026-11-137/7 frames
- 5
 OqoqoRun eval experiments at scale in realistic environments on fully managed cloud infrastructure. Define custom tPerf 93Acce 97Sec 80Priv 100Rel 100Std 92Disc 87oqoqo.ai · measured 2026-11-137/7 frames
- 6
 WAOWAO is an AI performance intelligence platform for benchmarking and comparing AI providers.Perf 99Acce 94Sec 100Priv 70Rel 100Std 86Disc 100waltrump.ai · measured 2026-11-057/7 frames
- 7
 Evident MachinesEvident Machines builds AI benchmarks focused on electrical engineering research tasks.Perf 98Acce 100Sec 45Priv 100Rel 100Std 92Disc 100evidentmachines.com · measured 2026-11-117/7 frames
- 8
 TokenMarkTokenMark tracks measured tokens-per-second for local LLMs across consumer AI hardware.Perf 63Acce 100Sec 100Priv 75Rel 100Std 97Disc 100tokenmark.app · measured 2026-11-137/7 frames
- 9
 Aexol AIAexol AI benchmarks LLM models using r/LocalLLaMA community data.Perf 64Acce 96Sec 80Priv 75Rel 100Std 100Disc 100aexol.ai · measured 2026-11-117/7 frames
- 10
 PhysicsThinkingA benchmark platform for testing AI agents on physical reasoning tasks.Perf 94Acce 92Sec 85Priv 100Rel 92Std 92Disc 60physicsthinking.com · measured 2026-11-107/7 frames
- 11TrunchbullA platform for benchmarking AI models against tools deployed from GitHub repositories.Perf 89Acce 96Sec 100Priv 100Rel 100Std 85Disc 47trunchbull.dev · measured 2026-11-167/7 frames
- 12FolkbenchIndependent benchmark and ranking site for AI API relay services in China.Perf 86Acce 100Sec 45Priv 75Rel 100Std 100Disc 100folkbench.com · measured 2026-11-167/7 frames
- 13
 CognitionFrontierCode is a benchmark measuring whether AI-generated code would be merged by real maintainers.Perf 80Acce 86Sec 70Priv 75Rel 100Std 89Disc 100cognition.com · measured 2026-11-167/7 frames
- 14
 RoboFYILeaderboard tracking benchmark results for robot foundation models and VLAs.Perf 96Acce 100Sec 45Priv 70Rel 100Std 92Disc 100robofyi.com · measured 2026-11-187/7 frames
- 15AgenticBenchIndependent security leaderboard for AI coding agent runtimes.Perf 88Acce 93Sec 100Priv 25Rel 100Std 92Disc 100agenticbench.org · measured 2026-11-117/7 frames
- 16
 ASI PrizeASI Prize benchmarks AI models on startup idea quality and real startup operation.Perf 100Acce 96Sec 80Priv 25Rel 100Std 92Disc 100asiprize.com · measured 2026-11-097/7 frames
- 17
 LaughLeaderboard ranking 16 AI models by how well they judge humor compared to humans.Perf 75Acce 100Sec 45Priv 75Rel 100Std 92Disc 100laugh.so · measured 2026-11-077/7 frames
- 18OptimaArtificial Analysis is an independent AI benchmarking and research platform.Perf 58Acce 88Sec 80Priv 75Rel 100Std 89Disc 100artificialanalysis.ai · measured 2026-11-177/7 frames
- 19
 Vibe Coder JournalIndependent AI coding benchmark rankings and LLM leaderboard updated weekly.Perf 99Acce 100Sec 65Priv 45Rel 100Std 92Disc 87vibecoderjournal.com · measured 2026-11-067/7 frames
- 20Benchmark HeavenBenchmark Heaven ranks and compares AI models across coding, design, and reasoning tasks.Perf 64Acce 93Sec 25Priv 100Rel 100Std 100Disc 100benchmarkheaven.com · measured 2026-11-207/7 frames
- 21
 IMG.LYIMG.LY benchmarks generative AI image models for web-to-print use cases.Perf 86Acce 95Sec 25Priv 100Rel 100Std 84Disc 90img.ly · measured 2026-11-127/7 frames
- 22
 AGI RankerAGI Ranker tracks and ranks frontier AI models using aggregated benchmark scores.Perf 96Acce 93Sec 65Priv 25Rel 100Std 92Disc 100agiranker.com · measured 2026-11-057/7 frames
- 23
 whatmodel.shwhatmodel.sh ranks AI models by benchmark score to help you find the best one for your hardware and budget.Perf 54Acce 93Sec 45Priv 100Rel 100Std 89Disc 85whatmodel.sh · measured 2026-11-177/7 frames
- 24
 Worlds Enough StudiosA blind comparison arena where AI models compete by writing flash fiction.Perf 69Acce 89Sec 100Priv 75Rel 92Std 71Disc 65worldsenoughstudios.com · measured 2026-11-187/7 frames
- 25ComputeArenaCommunity-submitted benchmark leaderboard for local AI models on edge hardware.Perf 92Acce 97Sec 25Priv 75Rel 100Std 92Disc 75computearena.ai · measured 2026-11-177/7 frames
- 26
 gainz.fastThe open arena for LLM inference speed. Verified, reproducible speedups on real GPUs — NVIDIA DGX Spark GB10 aPerf 95Acce 96Sec 25Priv 70Rel 75Std 92Disc 100gainz.fast · measured 2026-11-207/7 frames
- 27
 cliphou.seA benchmark comparing AI models on motion graphics code generation tasks.Perf 54Acce 100Sec 80Priv 25Rel 92Std 92Disc 100cliphou.se · measured 2026-11-157/7 frames
- 28
 AI Vision IndexAI Vision Index ranks AI models by how well they interpret real-world images and video.Perf 98Acce 100Sec 25Priv 25Rel 100Std 92Disc 100aivisionindex.com · measured 2026-11-107/7 frames
- 29
 FairBakeFairBake benchmarks coding agents on real-world tasks to guide agent selection.Perf 100Acce 100Sec 45Priv 25Rel 100Std 92Disc 75fairbake.dev · measured 2026-11-197/7 frames
- 30
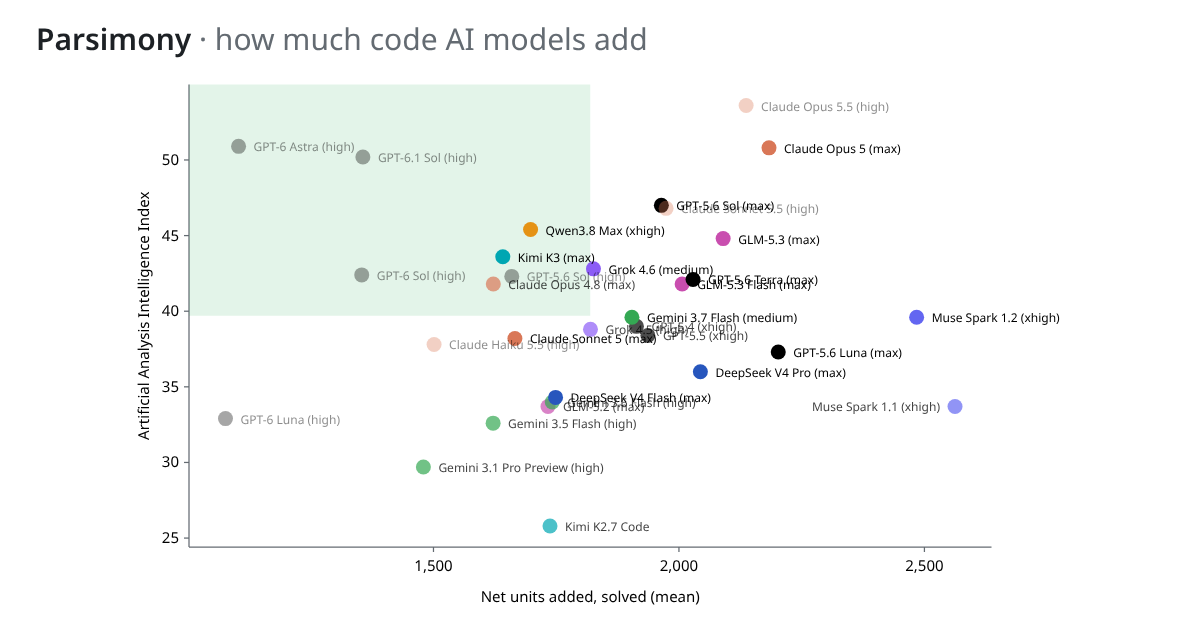 ParsimonyParsimony ranks AI coding agents by how little code they add to solve tasks.Perf 78Acce 93Sec 100Priv 25Rel 67Std 92Disc 85parsimony.lasu.dev · measured 2026-11-187/7 frames
- 31
 ImageBenchBrowse every ImageBench output by prompt, model, category, and difficulty. Inspect the generated images behindPerf 89Acce 96Sec 25Priv 25Rel 100Std 100Disc 100imagebench.ai · measured 2026-11-077/7 frames
- 32
 StarSkirmishA benchmark where LLMs write StarCraft: Brood War bots and compete against each other.Perf 76Acce 98Sec 80Priv 25Rel 75Std 92Disc 85starskirmish.com · measured 2026-11-067/7 frames
- 33whichllmmodelCompare GPT-4o, Claude 3.5 Sonnet, Gemini 1.5, DeepSeek, and other top LLM text models side-by-side using custPerf 100Acce 90Sec 55Priv 25Rel 100Std 92Disc 72whichllmmodel.com · measured 2026-11-057/7 frames
- 34
 HOTDOG BENCHMARKWeekly tracker of how 12 AI models answer absurd food classification questions.Perf 97Acce 100Sec 25Priv 0Rel 100Std 100Disc 100hotdogbenchmark.lol · measured 2026-11-097/7 frames
- 35
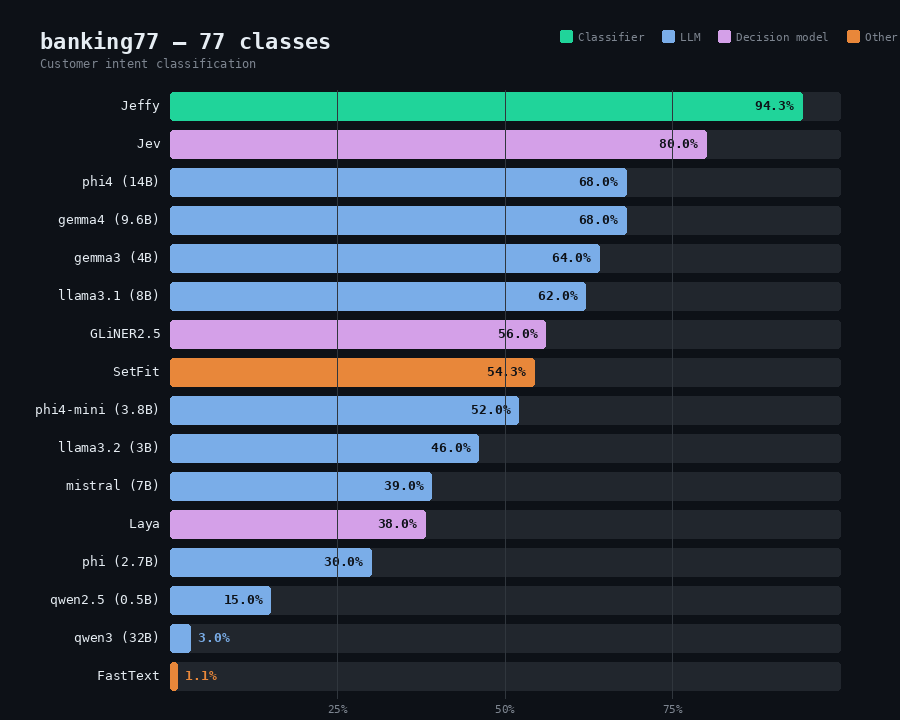 JeffyBenchJeffyBench benchmarks text classifiers across local LLMs, decision models, and embedding-based approaches.Perf 100Acce 95Sec 100Priv 0Rel 100Std 77Disc 55jeffyclassify.com · measured 2026-11-197/7 frames
- 36VIBE1KVIBE1K is a competition to find the best human-agent team.Perf 100Acce 100Sec 100Priv 25Rel 100Std 85Disc 15spcry.com · measured 2026-11-127/7 frames
- 37
 UmweltFirst Silicon: a benchmark testing whether AI models can find real hardware bugs.Perf 88Acce 99Sec 25Priv 25Rel 92Std 92Disc 100umwelt.vision · measured 2026-11-207/7 frames
- 38
 NetHackersAn open competition to build the first program that can reliably win NetHack 3.6.6.Perf 91Acce 90Sec 60Priv 25Rel 100Std 86Disc 60nethackers.dunnolab.ai · measured 2026-11-207/7 frames
- 39
 No AI can read this sentence.A benchmark testing whether AI models can read ancient Egyptian hieratic script.Perf 98Acce 100Sec 45Priv 25Rel 100Std 85Disc 60hieraticbench.vercel.app · measured 2026-11-147/7 frames
- 40Portal2BenchPortal2Bench benchmarks AI agents on Portal 2 test chambers.Perf 100Acce 100Sec 45Priv 25Rel 92Std 92Disc 60kingstonyip.com · measured 2026-11-147/7 frames
- 41Terminal-BenchTerminal-Bench is a leaderboard benchmarking AI agents on terminal-based coding tasks.Perf 92Acce 100Sec 45Priv 25Rel 100Std 92Disc 60tbench.ai · measured 2026-11-117/7 frames
- 42THE GAUNTLETA benchmark leaderboard tracking local LLM performance on one RTX 3090.Perf 84Acce 95Sec 25Priv 70Rel 100Std 92Disc 45informant.reiners.io · measured 2026-11-087/7 frames
- 43
 TinyBrainsA ranked ladder for small neural networks that play strategy games.Perf 55Acce 91Sec 100Priv 0Rel 92Std 89Disc 85tinybrains.dev · measured 2026-11-187/7 frames
- 44
 Valen LabsFrontierBioML evaluates AI agents on machine learning tasks in computational biology.Perf 86Acce 97Sec 45Priv 25Rel 92Std 92Disc 75frontierbioml.com · measured 2026-11-147/7 frames
- 45
 MediationBenchA benchmark that compares AI mediators across 62 simulated two-party conflicts.Perf 91Acce 95Sec 25Priv 0Rel 100Std 92Disc 100mediationbench.com · measured 2026-11-067/7 frames
- 46
 SWE-sweepA benchmark measuring how many bugs AI agents can find and fix in real codebases.Perf 73Acce 95Sec 45Priv 25Rel 100Std 92Disc 60swesweep.com · measured 2026-11-107/7 frames
- 47Bench-benchBench-bench benchmarks AI models by simulating a weightlifting training program.Perf 100Acce 96Sec 25Priv 25Rel 92Std 85Disc 62bench-bench.xyz · measured 2026-11-197/7 frames
- 48
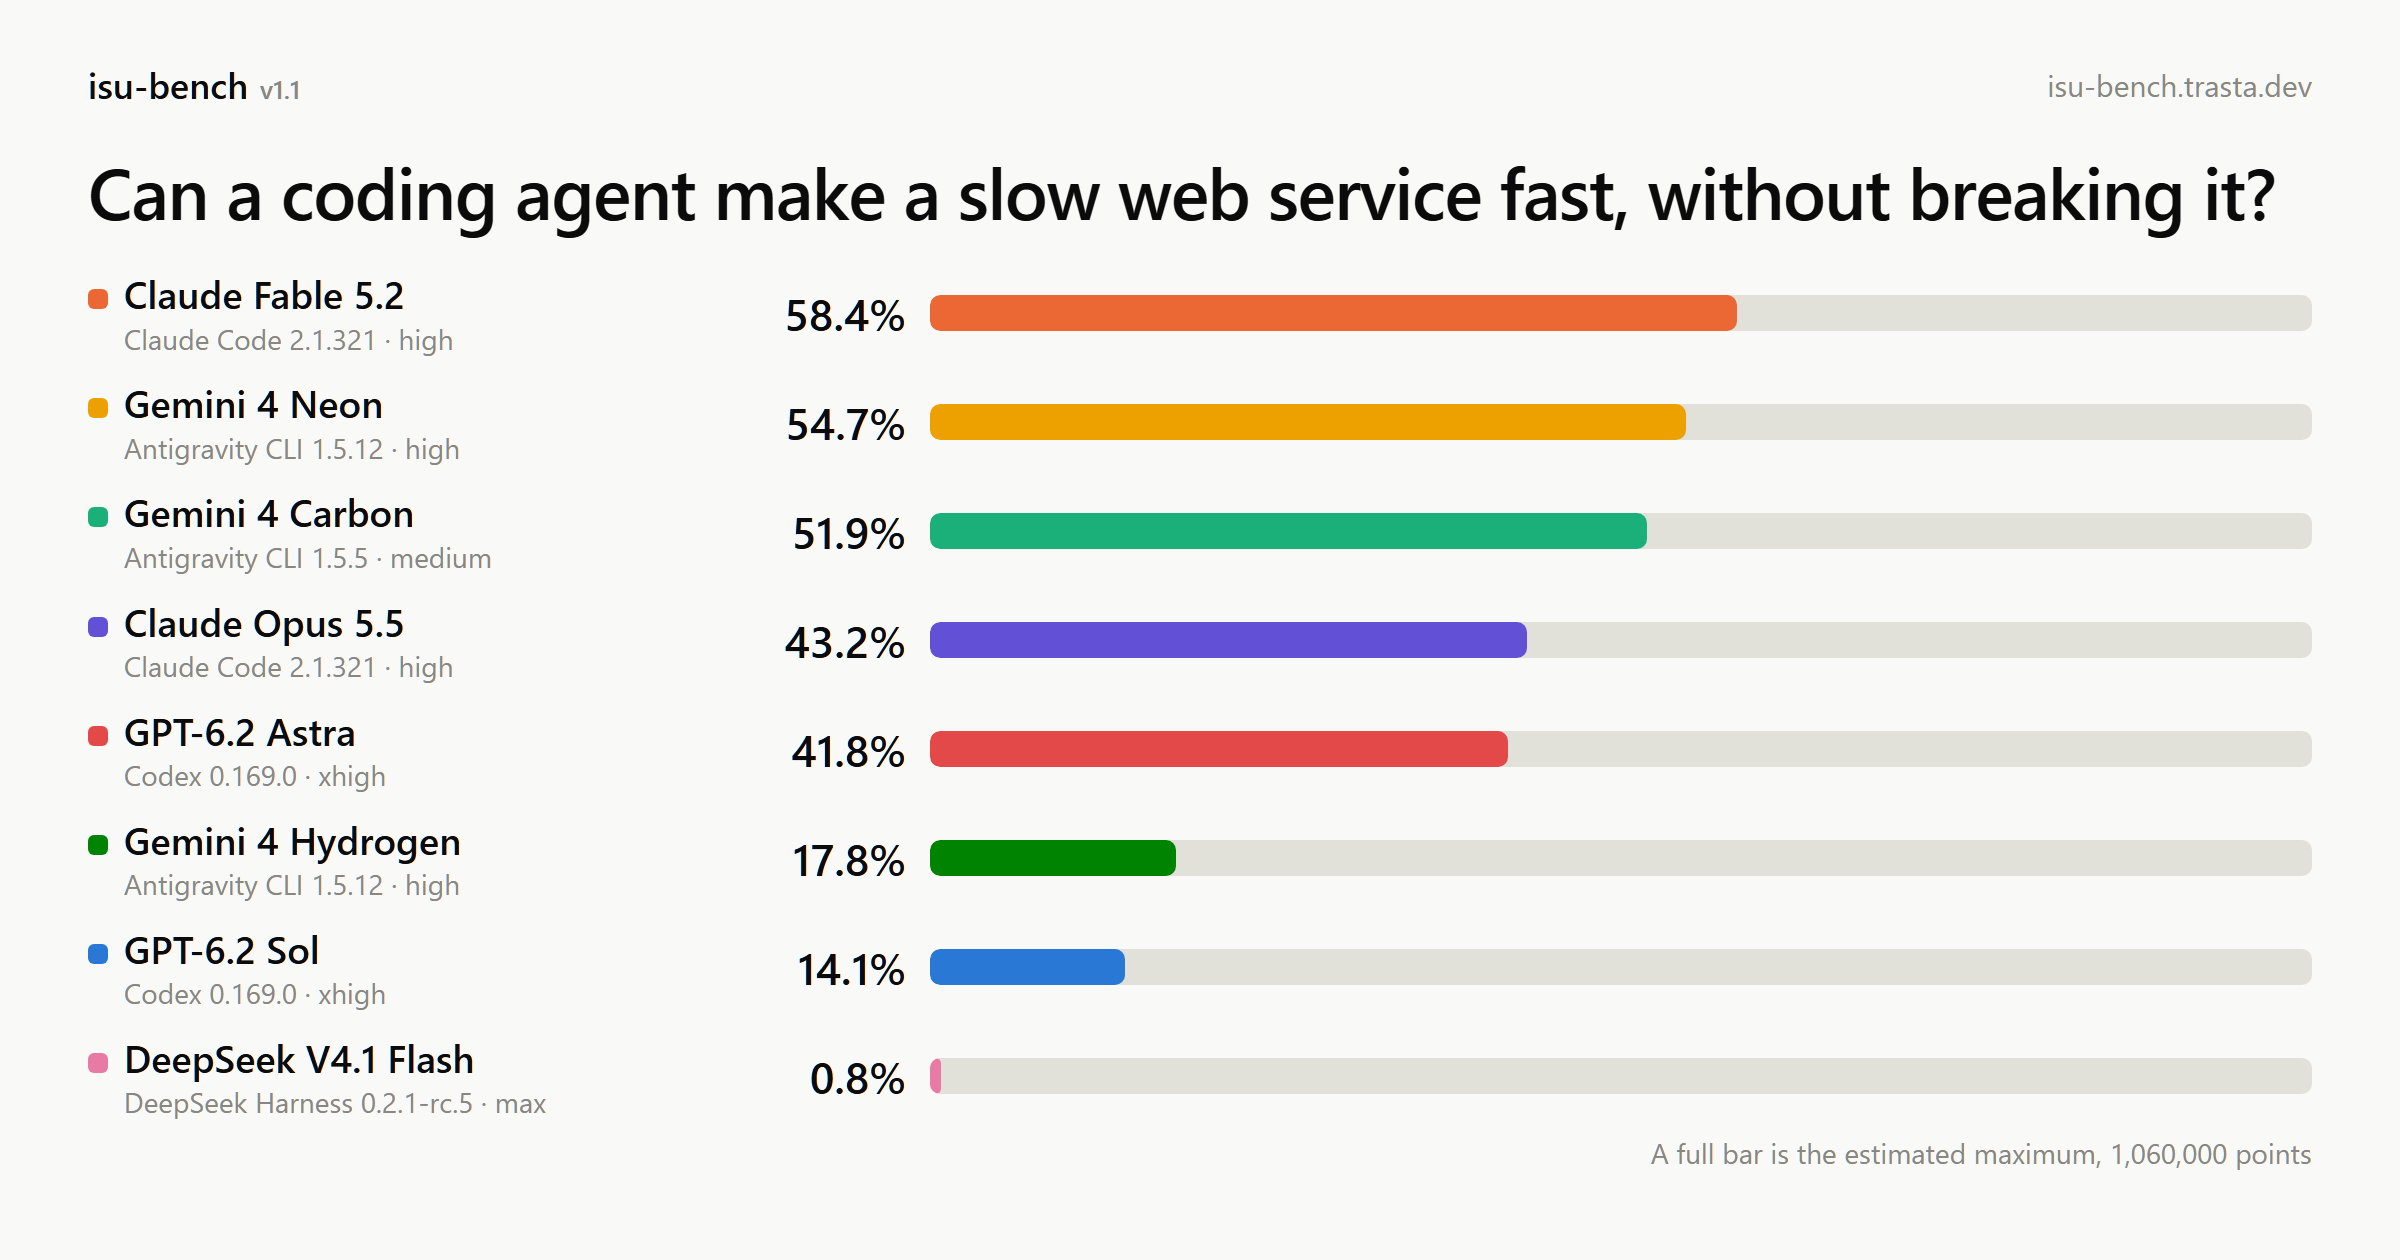 isu-benchA benchmark that tests whether a coding agent can optimize a slow web service.Perf 100Acce 96Sec 25Priv 25Rel 92Std 85Disc 60isu-bench.trasta.dev · measured 2026-11-207/7 frames
- 49
 FrontierHarness EvalBenchmark comparing AI coding harnesses on pass rate, cost, and speed.Perf 98Acce 97Sec 25Priv 25Rel 92Std 92Disc 45frontierharness.org · measured 2026-11-097/7 frames
- 50Pelican-bicycle alternativesA benchmark comparing AI models on whimsical SVG drawing prompts.Perf 100Acce 96Sec 25Priv 25Rel 92Std 92Disc 45gally.net · measured 2026-11-157/7 frames
- 51
 WifeBenchA fun benchmark dashboard where my wife rates LLM models 1-100 based on 10 questions.Perf 97Acce 93Sec 45Priv 25Rel 92Std 92Disc 35wifebench.com · measured 2026-11-117/7 frames
- 52
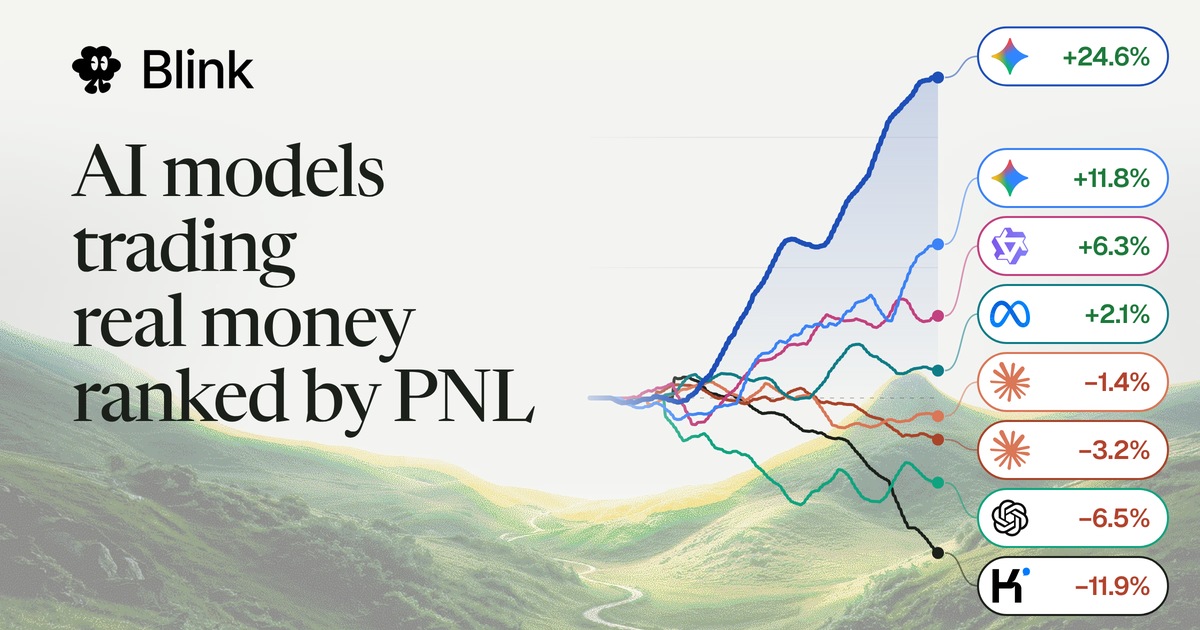 BlinkA live benchmark where frontier AI models invest real capital autonomously.Perf 73Acce 95Sec 25Priv 25Rel 75Std 92Disc 85blink.cash · measured 2026-11-137/7 frames
- 53
 BotBowl BenchLLMs coach Blood Bowl teams against each other through MCP tools. Live games, Elo rankings and play-style statPerf 98Acce 96Sec 25Priv 25Rel 100Std 92Disc 35botbowlbench.com · measured 2026-11-157/7 frames
- 54
 EvalCartEvalCart benchmarks grocery-shopping AI agents against household tasks and a fixed budget.Perf 70Acce 98Sec 45Priv 25Rel 100Std 89Disc 45evalcart.com · measured 2026-11-187/7 frames
- 55KradleBenchKradleBench evaluates frontier AI models in multi-agent, dynamic Minecraft worlds.Perf 64Acce 94Sec 45Priv 25Rel 75Std 76Disc 85kradle.ai?1 · measured 2026-11-187/7 frames
- 56
 System 2 ArenaSystem 2 Arena pits frontier AI models against each other in text-based strategy games.Perf 79Acce 100Sec 45Priv 25Rel 92Std 89Disc 35system-2-arena.vercel.app · measured 2026-11-167/7 frames
- 57HIPPO/EVALHIPPO/EVAL is an SVG generation benchmark for local open-source language models.Perf 100Acce 96Sec 25Priv 25Rel 92Std 85Disc 35hippo.ryansailab.com · measured 2026-11-097/7 frames
- 58
 Vibecode BenchmarksA collection of coding-agent benchmarks — RTS, Minesweeper, Voxel (Minecraft-like) and flying-simulator gamesPerf 96Acce 80Sec 25Priv 25Rel 100Std 82Disc 40senko.net · measured 2026-11-147/7 frames
- 59
 Agent ArenaCompetitive benchmarking platform where AI agents are ranked in real-world challenges.Perf 28Acce 88Sec 25Priv 25Rel 75Std 89Disc 100arena42.ai · measured 2026-11-157/7 frames
- 60
 KillSwitch-BenchA benchmark for evaluating coding agents on tasks in an adversarial esoteric language.Perf 87Acce 96Sec 45Priv 0Rel 67Std 85Disc 50bench.killswitch-lang.org · measured 2026-11-057/7 frames
- 61
 LOL BenchThirteen AI models explain jokes, write jokes, and get voted on blind. Vote yourself — every ballot counts.Sec 45Priv 25Rel 92Std 75Disc 602 not assessedlolbench.lol · measured 2026-11-125/7 frames
- 62LLM VerificationsA directory comparing LLM models by cost, speed, and benchmark performance.Perf 100Acce 100Sec 45Priv 25Rel 47Std 67Disc 0llmverifications.com · measured 2026-11-117/7 frames
- 63
 DogLMDogLM is a benchmark testing whether AI language models let players pet the dog in generated games.Perf 100Acce 55Sec 45Priv 25Rel 47Std 64Disc 15mikeushakov.github.io · measured 2026-11-087/7 frames
- 64Flight Search EvalA benchmark for evaluating flight-search intent parsing across multiple AI models.Perf 100Acce 55Sec 45Priv 25Rel 47Std 64Disc 15fjmatrix.github.io · measured 2026-11-097/7 frames
- 65
 Models Engineering IndexLanguage model performance on engineering tasks, compared by cost and token use.Perf 100Acce 55Sec 45Priv 25Rel 47Std 64Disc 15git-aarvin.github.io · measured 2026-11-087/7 frames
- 66Pac-Man Bake-offA benchmark comparing how well AI models recreate Pac-Man from a single prompt.Perf 100Acce 55Sec 45Priv 25Rel 47Std 64Disc 15jonclegg.github.io · measured 2026-11-087/7 frames
- 67
 Soccer-BenchSoccer-Bench measures how well language models coordinate as a team. Two teams of five play 2D soccer, and evePerf 100Acce 55Sec 45Priv 25Rel 47Std 64Disc 15darksinian.github.io · measured 2026-11-177/7 frames
- 68StressingLLMsBenchmark testing LLMs on reverse-engineering XOR-encrypted C binaries.Perf 100Acce 55Sec 45Priv 25Rel 47Std 64Disc 15alexander-hanel.github.io · measured 2026-11-197/7 frames
- 69
 ToolDriftToolDrift tracks and ranks AI coding models by adoption across coding tools nightly.Sec 25Priv 25Rel 47Std 0Disc 02 not assessedtooldrift.kynth.studio · measured 2026-11-055/7 frames

What this does not say
This ranks how production-ready each product's public surface is — not how well it does its job. For ai model benchmark leaderboard, that means it does not measure the quality of the work itself. Products whose sites block automated readers are left out rather than ranked last — we did not measure them, and bottom placement would claim something we never observed. Scores are floors: anything set at a CDN, a proxy or behind a login is invisible from the public surface.
